Project Details
- Languages
- Python
- Service
- Predictive Modeling
- Ensemble Learning
- Hyperparameter Tuning
- Libraries
- XGBoost
- LightGBM
- scikit-learn
- scikit-optimize
- Pandas
- NumPy
- Matplotlib
- Seaborn
Description
This project predicts the U.S. Air Quality Index (AQI) from meteorological data sourced through the NASA POWER API and combined with EPA air quality records. A blending ensemble of XGBoost and LightGBM models, built in Python, forms the core of the predictor.
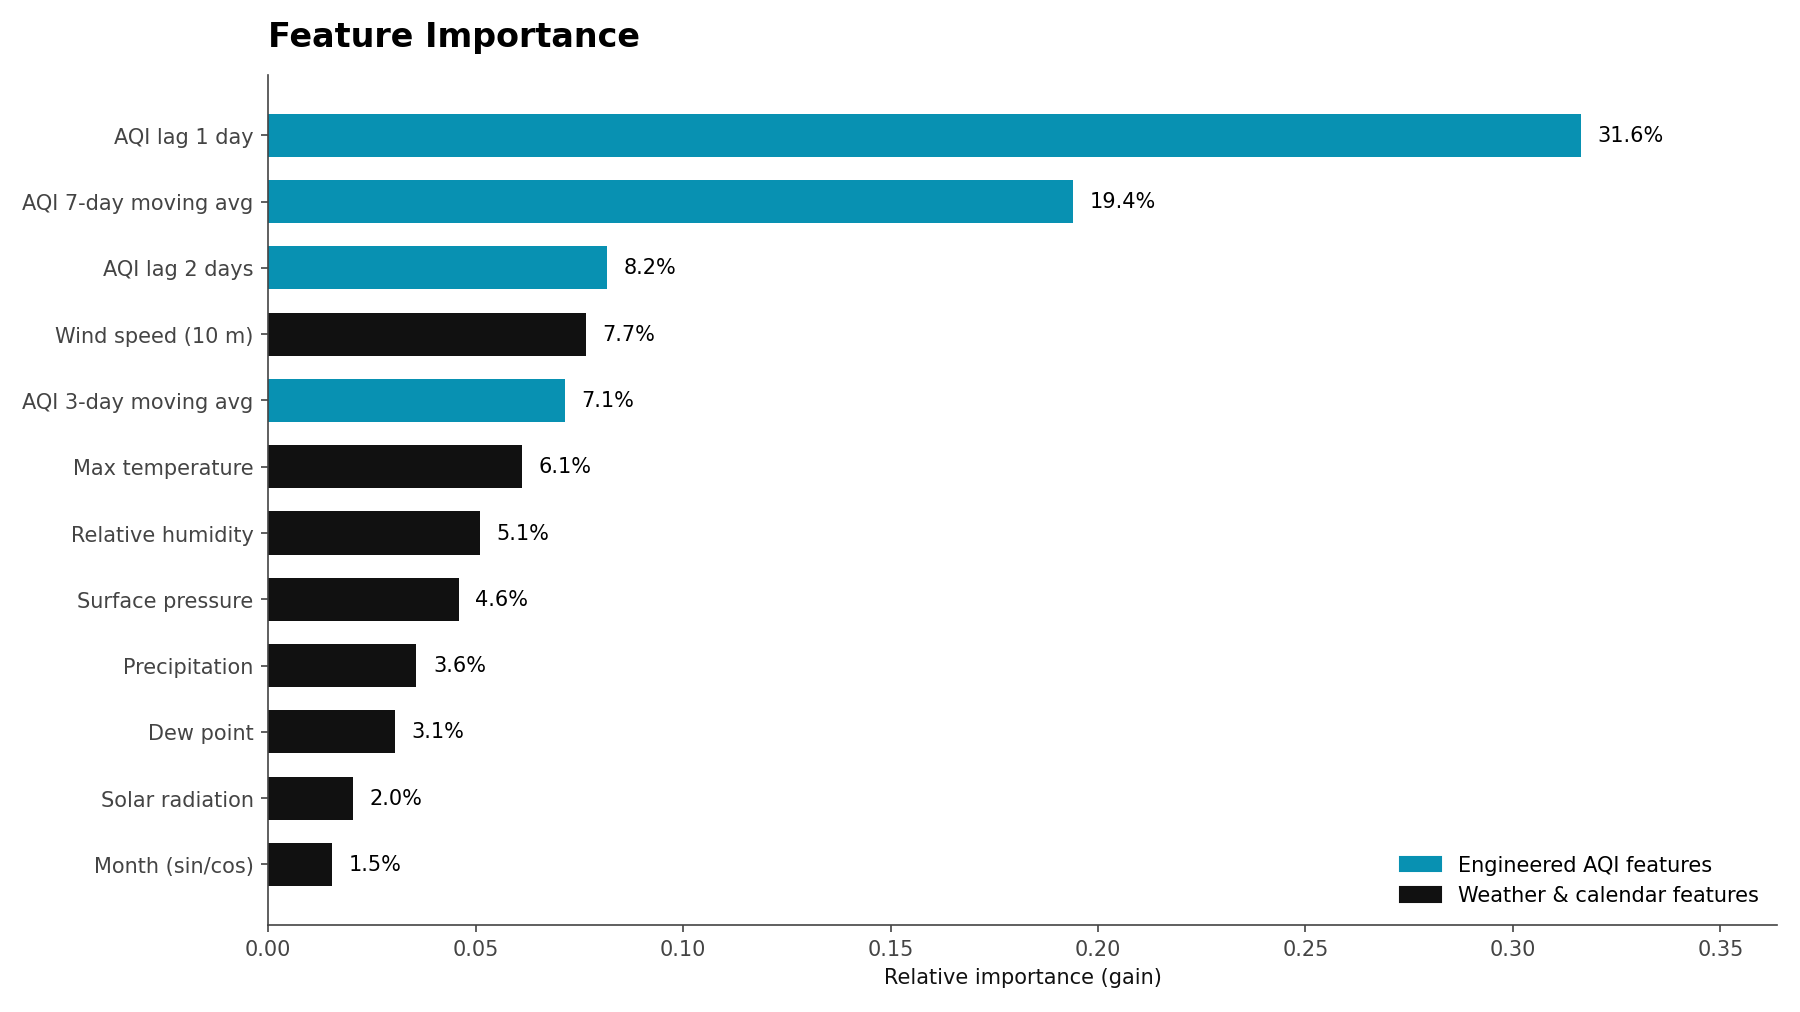
To improve accuracy, the models were tuned with Bayesian hyperparameter optimization (scikit-optimize), and the data was enriched with lagged AQI features and moving averages. Pandas and NumPy handled the data preparation, while scikit-learn covered splitting, cross-validation, and modeling.
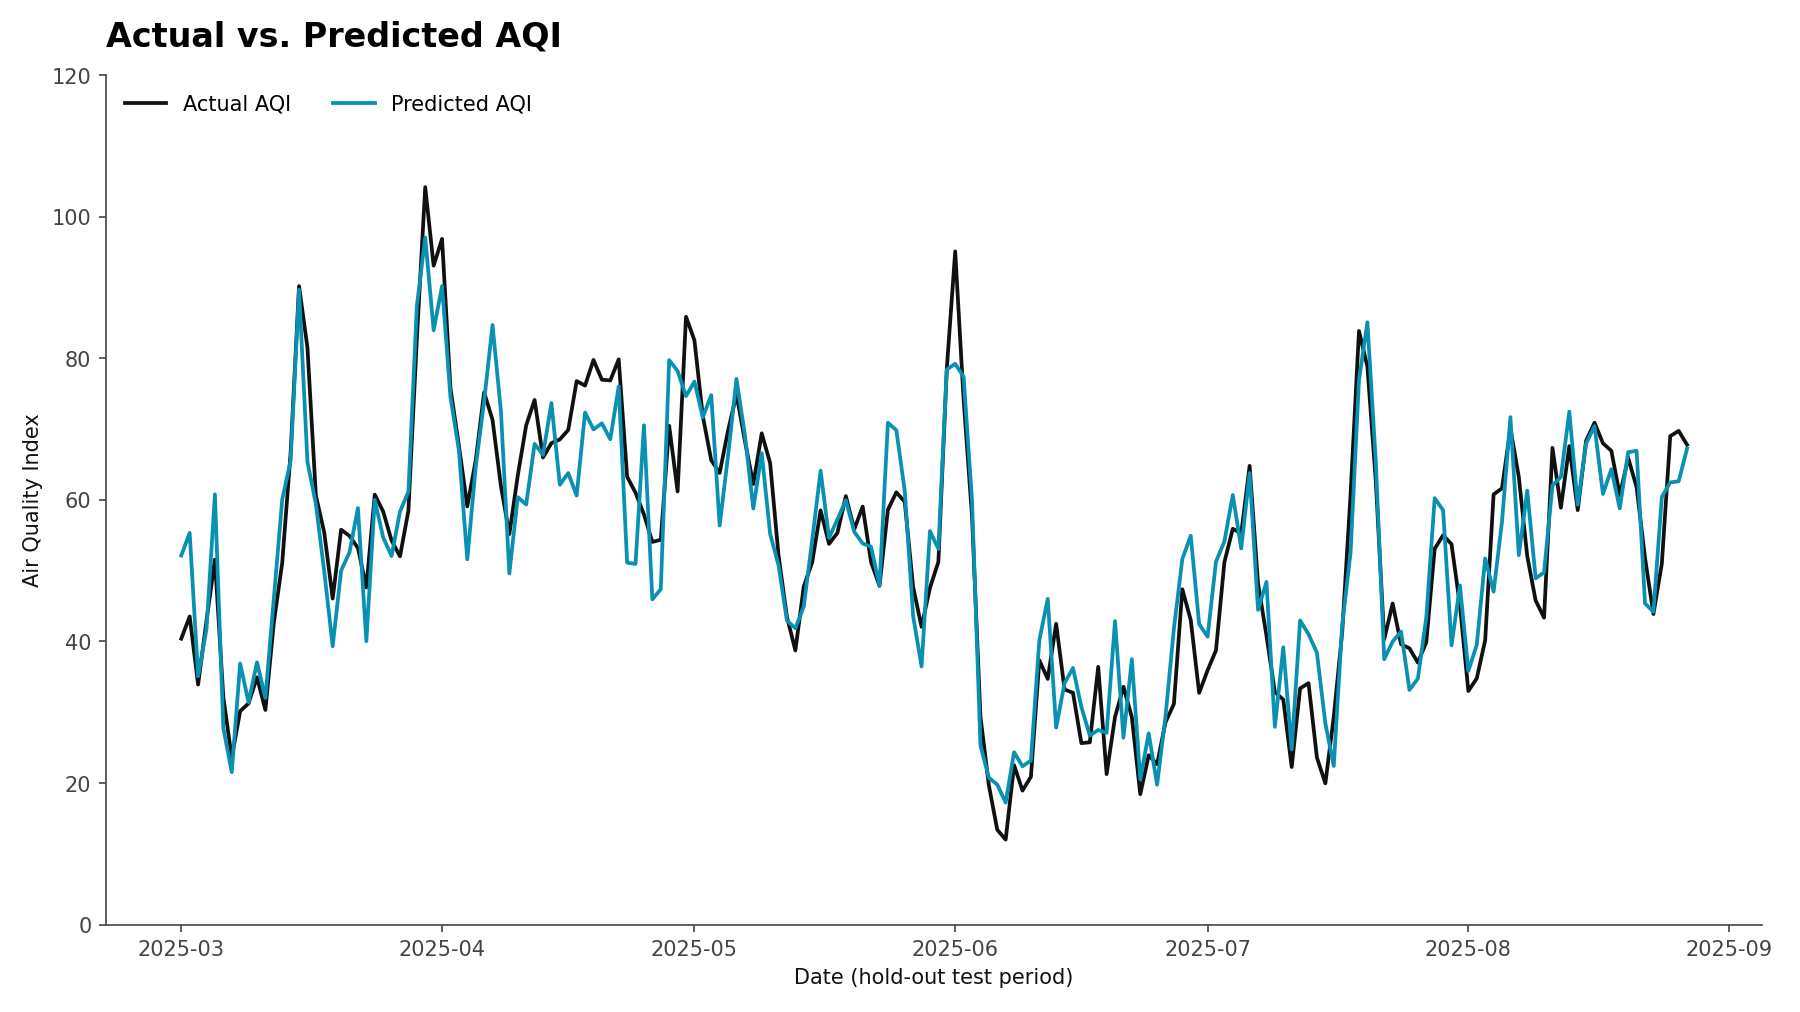
Performance was evaluated using RMSE, MSE, and R², and feature importance was used to see which variables drive the predictions. Matplotlib and Seaborn produced the visuals, and statsmodels and SciPy supported regression diagnostics such as variance inflation factors and normality testing.